Technical SEO checklist for web development projects
Technical SEO for web development makes public content reachable, understandable and consistent across URLs, page responses and navigation. It belongs in the build and release process rather than a last-minute plugin installation. This checklist focuses on the work a developer can verify: crawlable routes, rendered content, canonical signals, redirects, structured data and real production checks that keep private information protected.
Key takeaways
- Give each useful public page a stable URL and a crawlable internal path.
- Align status codes, canonical URLs, indexing rules and sitemaps.
- Verify the deployed response and keep private access control separate from SEO rules.
Define the public URL inventory and internal structure
List the pages the business wants people to discover: services, useful articles, public product information and contact routes. Give each a clear purpose. Keep client workspaces, account screens and private documents outside that public inventory. The architecture should help a visitor move from a broad subject to the specific service or answer they need without relying on a search box.
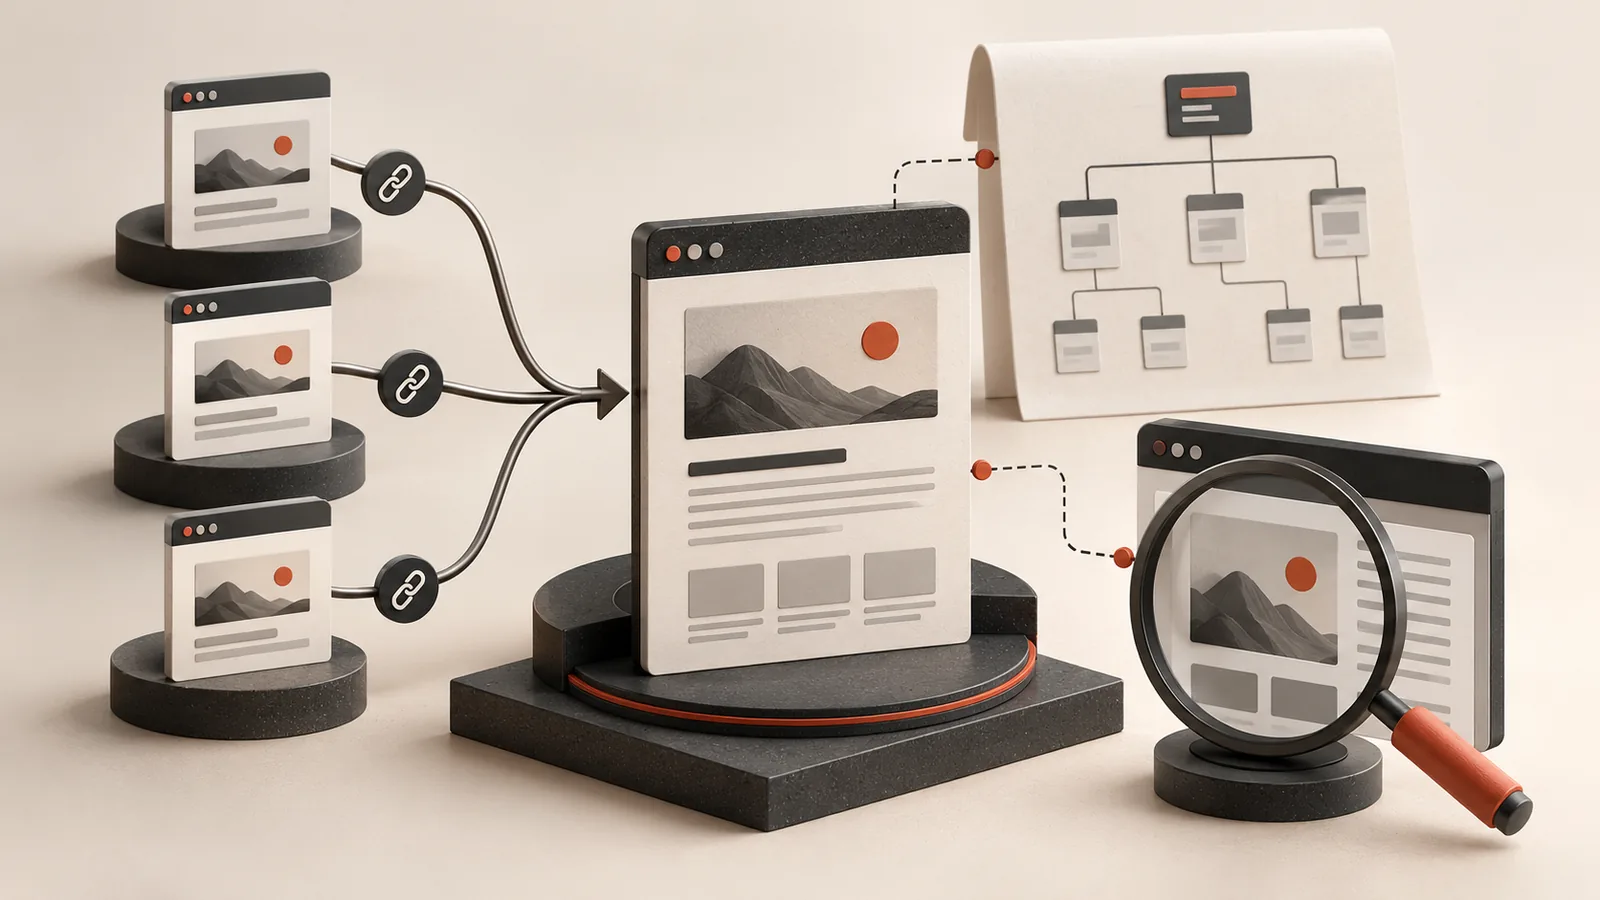
Google's developer guidance recommends links with crawlable anchor elements and URLs for distinct content. Apply that principle to the actual navigation, article relationships and service links. A page that exists in a CMS but has no useful path from another public page is harder for visitors to find too. Review the important journeys in the same architecture conversation as discovery and indexing.
- Keep one reviewable inventory of intended public routes.
- Use relevant internal links to connect services and deeper guides.
Verify responses and rendered page content
Request important URLs directly, including a deep article link opened in a fresh browser tab. Check that the server returns the intended page with an appropriate status. A missing page should not be presented as a successful generic page. Check the content and metadata in the delivered HTML and, where JavaScript affects them, the rendered result.
For JavaScript applications, plan how useful content reaches crawlers and link-preview systems. Server rendering or prerendering can be appropriate approaches, depending on the application. Do not assume that a single generic HTML shell communicates the purpose of every route. Inspect the real output after production build and deployment, including headings, canonical links and the main article text. A successful local navigation is only one part of the check.
| Route type | Expected behaviour | Check |
|---|---|---|
| Public service or article | Useful page with a consistent public URL | 200 response, matching content and canonical |
| Old address with an equivalent replacement | Permanent move to the relevant page | Redirect destination and updated internal links |
| Unknown or retired page without replacement | Real missing-page outcome | 404 response and helpful navigation |
| Private client content | Access enforced by the application | Unauthorised request cannot retrieve protected data |
- Test direct entry to deep links and unknown URLs.
- Inspect page-specific HTML as well as the interactive application.
Make canonical and indexing signals agree
Choose the preferred form of each public address and use it consistently in internal links, canonical tags and sitemaps. Review aliases, trailing slashes and duplicate paths intentionally. A canonical declaration is a signal about the preferred page, not a substitute for access control or a guarantee that a search engine will choose it. Google's duplicate-URL documentation explains the available consolidation methods.
Keep robots directives understandable. A crawl restriction and a noindex instruction serve different purposes; blocking a crawl can prevent the crawler from seeing a page-level instruction. Private information still needs authentication and authorisation regardless of what robots.txt says. Review staging restrictions before launch so public content does not accidentally remain excluded, and verify private routes without using discovery settings as their security boundary.
- Align public canonical URLs with links, redirects and sitemap entries.
- Test indexing instructions and access restrictions as separate responsibilities.
Describe each page accurately and provide useful context
Write a distinct title and description that reflect the actual page. Use one clear main heading and a structure that lets readers scan the topic. Give meaningful images appropriate descriptions and reserve their dimensions. Link related information where it helps a visitor decide what to do next. These are content and interface decisions as well as metadata tasks.
Use structured data only for facts supported by the visible page and the business's real identity. Article authorship, breadcrumbs and an accurate service description can clarify context. Invented ratings, reviews, locations or credentials create misleading signals. Keep dates honest and use updated dates when the content materially changes. A valid JSON document is not proof that a page is eligible for a particular search appearance or that it will receive one.
- Match metadata and structured data to visible, verifiable content.
- Give articles a clear author and related service or contact path.
Make SEO checks part of every meaningful release
Test the public inventory, important redirects, missing routes and private boundaries after deployment. Inspect the actual response headers and content rather than assuming the hosting environment behaves like the development server. Check mobile navigation, contact actions and image loading at the same time. Discovery that leads to a broken commercial journey has limited value.
Keep a record of changed URLs and content so later traffic movements can be investigated. Search tools can help show indexing and query changes, but a sitemap submission or crawler-compatible response does not prove ranking or traffic growth. Use production checks to establish what the site does correctly, then assess search outcomes separately. That distinction makes the technical work reviewable and keeps expectations grounded in evidence.
- Run route, redirect and private-access checks against the live host.
- Record release changes separately from observed search outcomes.
Sources and further reading
Primary documentation for the platform-specific details discussed in this article. The planning examples above are illustrative requirements, rather than client case studies.
Need technical SEO built into the development work?
Share the site, planned changes and any routes that must remain private. I can review the architecture and turn the important discovery and launch requirements into testable implementation work.
Discuss a projectFrequently asked questions
Practical answers to help you plan the next step.
From planning through launch. It is part of the build, not a final plugin or checklist afterthought.
No. Use structured data where it accurately describes the visible content and helps clarify the page type.
Yes, but important content, metadata and links must be easy for crawlers to render and understand. Static or prerendered output helps.